
How Does Agentic AI Work? The Complete Technical Guide
Most explanations of agentic AI focus on what agents can do, not how they do it. There is a gap between “the agent handles the whole workflow” and the mechanics behind it. That gap is where teams make good implementation decisions. It is also where poor ones cost money.
This article explains agentic AI from the inside out. It covers the core components, how they interact, the workflow patterns you see in production, and what a real agent execution looks like step by step.
What Is Agentic AI, and How Does It Work?
What makes an AI system “agentic”?
An AI system is agentic when it pursues a goal rather than answers a question. For example: a standard language model takes an input and produces an output. So just one interaction, and then it stops. An agentic system works differently.
It receives a goal, decides what steps reach it, and calls tools to run those steps. It adjusts when conditions change. And it keeps going until the task is done or it needs to escalate. So the threshold is simple. A system becomes agentic when the AI directs its own process and no longer waits for a human to start every step.
What makes this work is reasoning and the agent does not just fire off tool calls. It reasons about the goal, decides on an action, observes the result, then reasons again about what to do next. This loop is the ReAct pattern: reason, act, observe, repeat. And the agent can judge its own output along the way.
So it checks whether a step actually moved it closer to the goal, catches its own mistakes, and corrects course before continuing. That self-evaluation is a large part of why an agentic system handles messy, real-world tasks better than a single model call.
This is the foundation behind every agentic AI system in production.
How does it differ from a chatbot or copilot?
The distinction comes down to who controls the next step. A chatbot responds to what you ask. A copilot suggests what you might do next, then waits for your approval. But an agentic system decides the next step itself, based on what just happened.
It executes the action, evaluates the result, and decides what comes next. So the decision comes from the system. That is the difference.
What is the difference between an agentic workflow and an autonomous agent?
The clearest distinction here is a precise one. Workflows follow predefined code paths to orchestrate LLMs and tools. Agents let the LLM direct its own process and tool use at runtime. Both are agentic systems.
The split is simple: a workflow fixes the sequence of steps in advance, and an agent decides it at runtime. This follows Anthropic’s framework for agentic systems.
When should a team choose agentic AI over a simpler approach?
Agentic complexity has costs: higher latency, higher operating expense, and more failure modes to manage. So our guidance is simple. Find the simplest solution that works, and add complexity only when you need it. For many use cases, a single well-optimised LLM call with the right context is enough.
Agentic systems earn their place when the task spans multiple steps. They also fit when the work crosses several systems, cannot be fully predefined, and scales enough to justify the architecture.

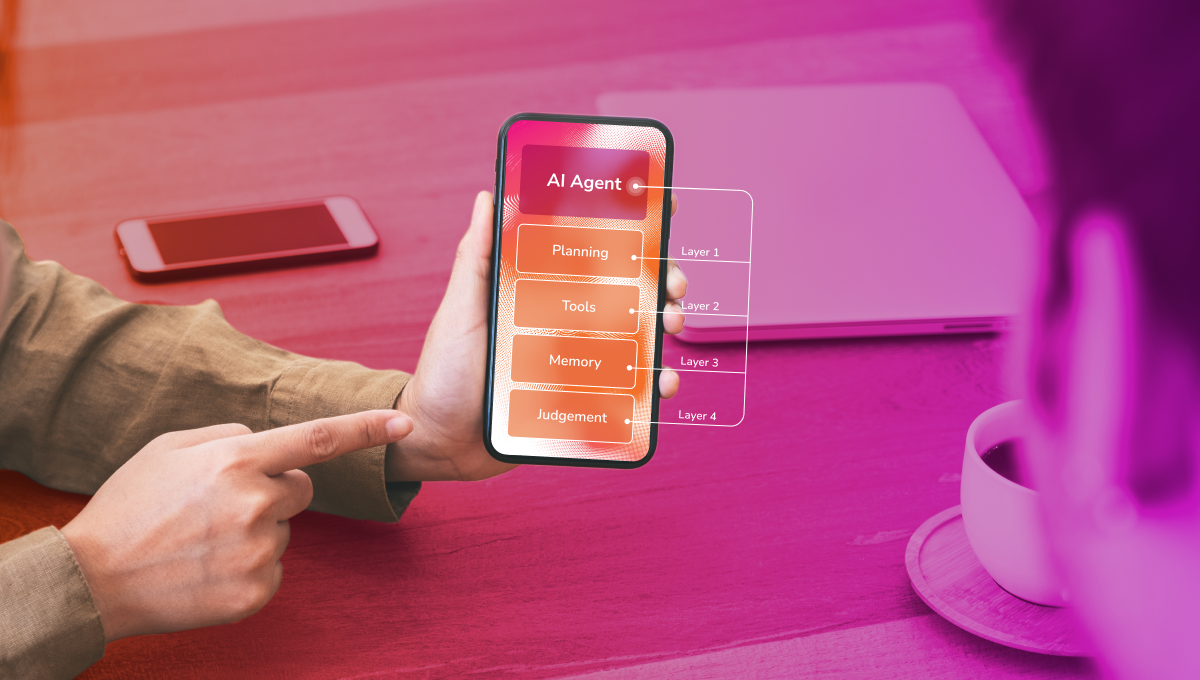
The Four Layers Every Agentic AI System Has
An AI agent that works in production combines four distinct capabilities. Looking at each one separately shows where deployments succeed and where they fail.
Planning: turning a goal into a sequence of steps
Take a request like “process this refund.” The planning layer breaks it into specific steps: verify the customer, check the order and return policy, validate the payment method, execute the refund, send confirmation, and log the action. Good planning produces agents that follow a logical path.
Poor planning produces agents that take odd routes, repeat steps, or get stuck in loops. The planning layer leans on the LLM’s ability to reason about goals and constraints at once.
Tools: connecting the agent to real systems
The planning layer decides what to do. The tool layer does it. Tools connect the agent to the systems it acts on: CRM records, ERP databases, APIs, email servers, payment processors, and audit logs. The breadth and reliability of this layer separates an agent that demos well from one that ships.
An agent with shallow tool access can impress in a controlled demo. Then it fails in a live one, because the action it needs has no reliable tool behind it.
Memory: carrying context across steps
An agent working a multi-step workflow must remember step two when it reaches step eight. Memory handles this within a task. For longer-horizon work, it carries context across sessions too. So memory is the most common source of production failures.
For example: an agent that loses context either fails outright or, worse, continues on wrong assumptions. Like people, it uses short-term memory for the current task. Long-term memory draws on stored knowledge, past interactions, and organisational data.
This is where a sound knowledge and memory architecture earns its keep.
Judgement: deciding when to act, escalate, or stop
Judgement separates production agents from impressive demos. It is the system’s ability to know when it is done, when to ask for clarification, when to escalate to a human, and when to refuse an action beyond its authorised scope. This ability has to adapt to circumstances.
Without judgement, an agent that meets an ambiguous case either stops at random or proceeds with false confidence. Both are expensive in production.
The Augmented LLM: The Core Building Block
Before workflows and multi-agent systems comes one foundational element: the augmented LLM. It is a large language model enhanced with retrieval, tools, and memory. This is the basic building block of every agentic system.
Retrieval: giving the agent relevant context
Retrieval connects the agent to knowledge it never trained on: internal documents, live data feeds, customer records, product catalogues, and regulatory standards. Without retrieval, the agent reasons only about what it already knows.
With it, the agent can pull in specific, current, organisational information and use it in every decision.
Tools: converting reasoning into action
Tools turn the agent’s decisions into operations in real systems: database queries, API calls, form submissions, file operations, and calendar entries. For example: Model Context Protocols give agents a standard way to connect to tool ecosystems.
That removes custom integration work for each new connection.
Memory: maintaining state across steps
Memory lets the agent carry what it learns from each step through the rest of the workflow. Without persistence, every tool call happens in isolation. With memory, the agent builds a coherent picture as it goes.
So it avoids contradicting itself or repeating work.
How Agentic AI Executes a Real Task: Step by Step
The best way to understand how agentic AI works is to follow a real execution. The example below walks through a customer requesting a refund. The request: a customer asks to return an order placed the previous week.
Step 1: Planning
The agent activates its planning layer. The LLM breaks the goal into a sequence: verify the customer, retrieve the order, check return eligibility, verify the payment method, execute the refund, send confirmation, and log the action.
Step 2: Identity and order retrieval
The agent calls the customer database tool to verify the account and pull the order details. Then it calls the order management system to confirm the order date, amount, and item category. It writes all of this to memory.
Step 3: Policy evaluation
Now the agent queries the return policy tool with the order date and item category. The policy returns a rule: this category allows returns within 30 days. The customer placed the order 8 days ago, so the condition is met.
Had they placed it 35 days ago, the judgement layer would escalate to a human with full context attached.
Step 4: Refund execution
The agent calls the payment processor tool with the order ID and refund amount. The processor returns a confirmation ID, and the agent writes it to memory.
Step 5: Confirmation and logging
Now the agent calls the email tool to send the customer a confirmation with the amount and timeline. It then calls the audit log tool to record the full transaction: customer ID, order ID, refund amount, policy basis, confirmation ID, and timestamp.
The whole execution runs across five systems in seconds. The human only sees it when the case falls outside the authorised scope.

The Five Agentic AI Workflow Patterns
Five workflow patterns cover most production agentic use cases. Each one suits a different problem structure.
Prompt chaining: sequential steps with gates
In prompt chaining, each step feeds its output into the next. The agent runs step one, checks the result, then moves to step two. You can add gates between steps to verify quality before continuing.
This pattern suits a fixed, predictable sequence where each step matters. It trades speed for accuracy by making each LLM call a narrower task. For example: draft a contract clause, check it against regulatory requirements, then format it for the document.
Routing: directing inputs to the right specialist
Routing classifies an incoming request and sends it to a specialist workflow or model. Instead of one generalist agent for everything, each input type goes to an agent tuned for it. For example: a support triage agent sorts requests into billing, technical, returns, or complaints.
Then it routes each one to the specialist best equipped to handle it.
Parallelisation: running multiple agents simultaneously
Parallelisation runs multiple agents at once rather than in sequence. There are two approaches. Sectioning splits a task into independent parts, runs them in parallel, then combines the results.
Voting runs the same task several times with different agents and takes the highest-confidence output. An example of sectioning: one agent reviews a contract and checks data protection, liability, and payment terms at the same time, then aggregates the findings.
An example of voting: three agents each check the same code for security flaws, and any finding flagged by two or more triggers a review.
Orchestrator-workers: dynamic task delegation
In the orchestrator-workers pattern, a central orchestrator LLM receives a goal. It decides how to break the goal down based on what it discovers, then delegates tasks to specialised worker agents.
So unlike prompt chaining, the orchestrator does not fix the sequence in advance. It decides at runtime which workers to call and in what order.
This pattern suits complex tasks where you cannot know the full scope upfront. For example: an agent implementing a feature change across a multi-file codebase.
The orchestrator assesses the codebase, finds the affected files, assigns each change to a worker, collects the results, and reviews the whole output.
Evaluator-optimiser: generating and refining in a loop
In the evaluator-optimiser pattern, one agent generates an output and a second agent checks it against defined criteria. If the output misses the mark, the evaluator gives specific feedback, and the generator revises it.
The loop continues until the output meets the standard. This pattern helps wherever quality is easier to judge after the fact than to specify upfront.
For example: one agent drafts a technical specification, and a second checks it against compliance and feasibility, feeding back gaps until it is complete.

Multi-Agent Systems: When One Agent Is Not Enough
Complex enterprise tasks often need several specialised agents working together, not one general-purpose agent doing everything.
Why specialisation produces better results
An agent tuned for return-policy queries beats a general service agent on return cases. An agent with deep access to financial systems handles invoice reconciliation more reliably than a general operations agent. So specialisation lets you scope, tune, and permission each agent for its specific job. It also lowers risk.
A single all-capable agent with access to every system is a large attack surface, and one failure can spread widely. Smaller specialised agents with narrow permissions are easier to audit and update, and they stay within a defined scope.
How agents coordinate
An orchestrator manages delegation. Worker agents complete discrete tasks and return results. A reviewer agent can check outputs before the system commits them. The orchestrator then synthesises results and decides whether the goal is met or whether more work is needed.
Ongoing monitoring through AgentOps keeps the system reliable as data, models, and workflows change after deployment.
What Agentic AI Cannot Do Well Yet
An honest account of how agentic AI works has to cover where today’s systems still fall short.
Long-horizon autonomous tasks remain hard. Research by Accenture and Wipro, cited by UiPath in January 2026, puts 70 to 80% of agentic initiatives short of enterprise-wide scale. Systems do well in narrow contexts.
But they struggle with tasks that run for hours without checkpoints, need genuinely novel planning, or rely on integrations that behave inconsistently.
Regulated environments need specific governance architecture that most standard platforms skip by default. Teams often bolt on auditable decision logs, role-based access controls, interruptible workflows, and data protection compliance after deployment. They should design these in from the start.
Planning limits are real, too. Agents do well when the goal is clear and the steps are broadly predictable. They get less reliable when a task needs reasoning about novel situations, long-term consequences, or highly ambiguous instructions.
What Building a Production-Grade Agentic AI System Involves
Understanding how agentic AI works is the first step toward building one that runs reliably in production. The gap between a working demo and a reliable system is where most enterprise deployments stall.
What a production-grade system requires
- a clearly scoped first workflow with a measurable outcome
- a data access layer connecting the agent to live systems
- memory architecture that fits the task’s complexity
- reliable tools covering every action the agent needs to take
- a governance layer that sets autonomous-action limits, escalation paths, and audit logging
- an observability layer so the team can monitor and debug the system
- a security audit covering prompt injection risks, permission scoping, and data handling
DAC builds custom agentic AI development for enterprise teams whose workflow, data, or compliance needs go beyond off-the-shelf platforms. The work starts with the augmented LLM foundation and the right agent pattern. It runs through to production deployment and ongoing support.
Build a production-grade agentic AI system
Talk to DAC about designing and deploying agentic AI for your workflow, from the augmented LLM foundation through to production.

Frequently Asked Questions
Q1: What large language model powers an agentic AI system?
A1: Match the model to the step. For demanding, multi-constraint reasoning, Claude Opus 4.8 is the strongest default and for easier routing or classification, Claude Sonnet 4.6 or Claude Haiku 4.5 keep latency and cost down. GPT-5.5 from OpenAI is also a capable alternative and Google’s Gemini 3.5 Flash suits high-volume routing. So the right pick depends on cost and the real goal (current comparisons: llm-stats.com and Azumo’s June 2026 ranking).
Beyond the specific model, any capable LLM can anchor the reasoning core. The choice depends on task requirements, cost, latency, and data-handling policies. Most teams use a frontier model for the main reasoning layer and route simpler steps to smaller, faster models to cut latency and cost. The model matters less than the tool layer, the memory architecture, and the workflow design around it.
Q2: How does an agentic AI maintain context across multiple steps?
A2: Three mechanisms maintain context. In-context memory holds the information in the current task session. External memory retrieval queries a knowledge base or database for relevant past information. Structured state management writes key findings to a persistent store the agent can query at each step. The right mix depends on the length and complexity of the task.
Q3: What happens when an agentic AI makes an error mid-workflow?
A3: A well-designed system handles errors at each tool call. It recognises when a step returns an unexpected result. And it has a defined escalation path when the task falls outside the agent’s authorised scope. So the agent detects the anomaly, writes context to the escalation record, and routes to a human reviewer with everything they need. But error handling is a design decision, and you have to implement it.
Q4: Is agentic AI the same as a large language model?
A4: A large language model is the reasoning engine inside an agentic system, not the system itself. The LLM only generates decisions, plans, and outputs. The agentic system wraps retrieval, tools, memory, and governance around it to turn those outputs into real actions. On its own, an LLM can produce useful text. But it cannot run a multi-step workflow across several enterprise applications.
Q5: How complex is it to build a custom agentic AI system?
A5: It depends on the workflow’s scope, the number of systems the agent touches, the data architecture, and the governance requirements. For example: a single well-scoped workflow with clean data and reliable APIs can be prototyped in weeks. An enterprise-wide multi-agent system with regulated data and complex integrations is a months-long engineering project. So start with the smallest scope that proves the concept. Then expand from a proven foundation.
Are you Ready to Discuss Your Project With us? If so, Simply Fill in the Form.
Contact us!
Send us an email: [email protected]